Internal Coper project
Rebuilding Coper's website and the system behind it
Coper rebuilt its own website — and rebuilt the way we build websites while doing it. The redesign is the part you can see; the system behind it is what actually changed.
- Project type
- Internal Coper project
- Capabilities
- Create · Grow · Automate
- Built with
- Astro · Cloudflare Workers · Cloudflare D1 · Cloudflare Pages/Assets · GitHub Actions · Google Search Console
Internal Coper project
A real system Coper built and runs for itself, rather than work delivered for a client.
Why this project exists
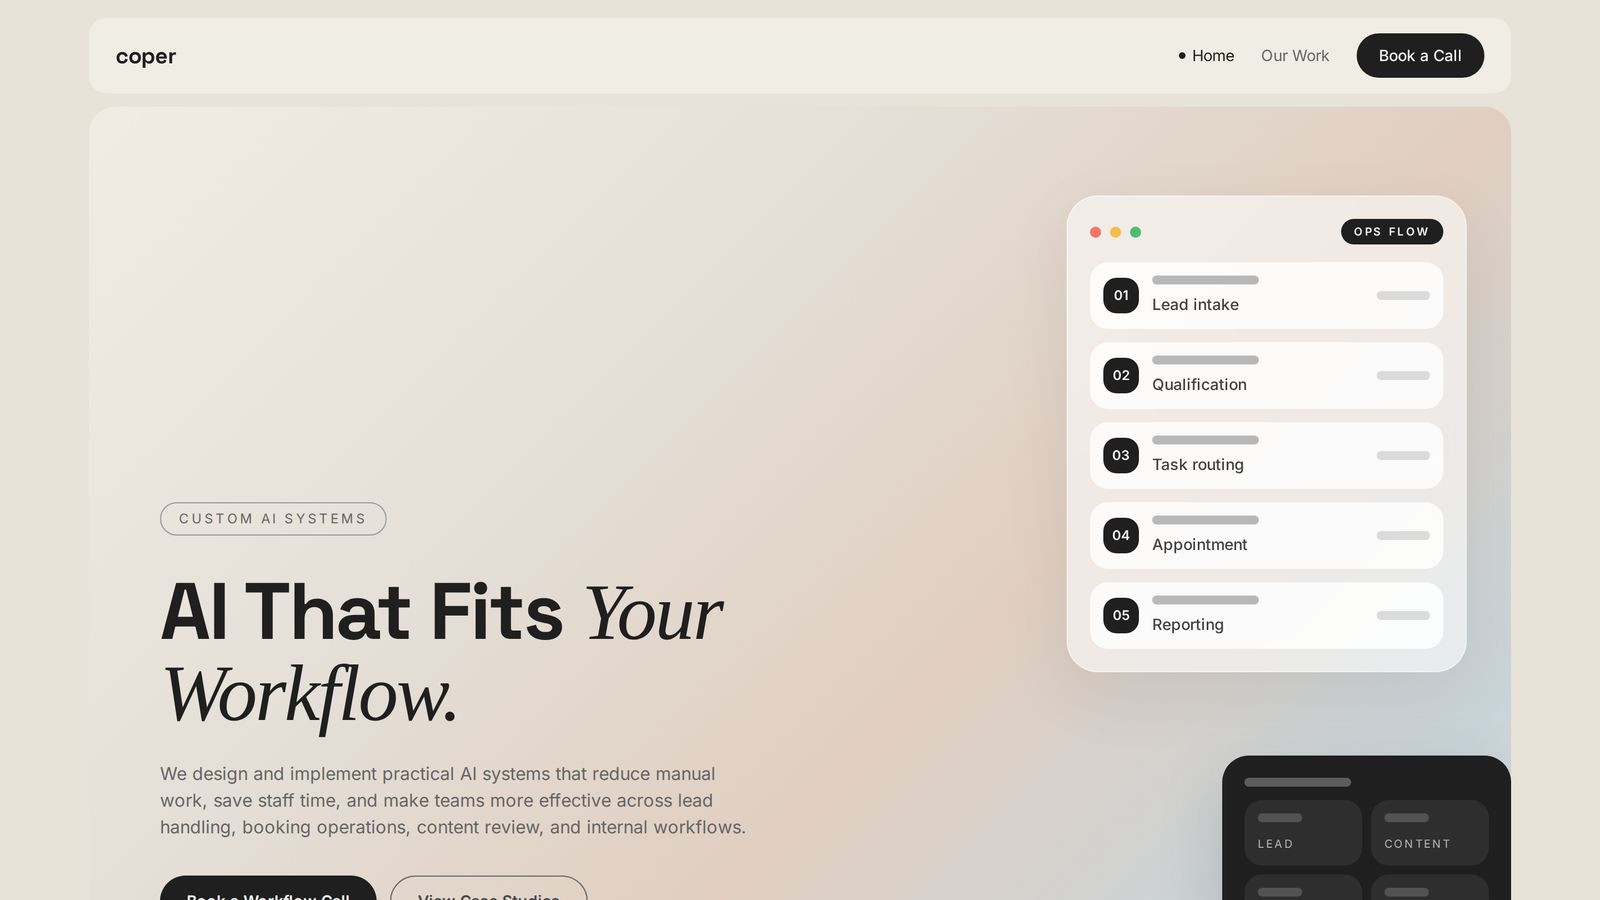
The old site introduced the company and offered a way to get in touch, and it did that job. But it was a single-page template site, and it still described custom AI systems while the work had grown into websites, software, marketing and automation delivered together.
The change
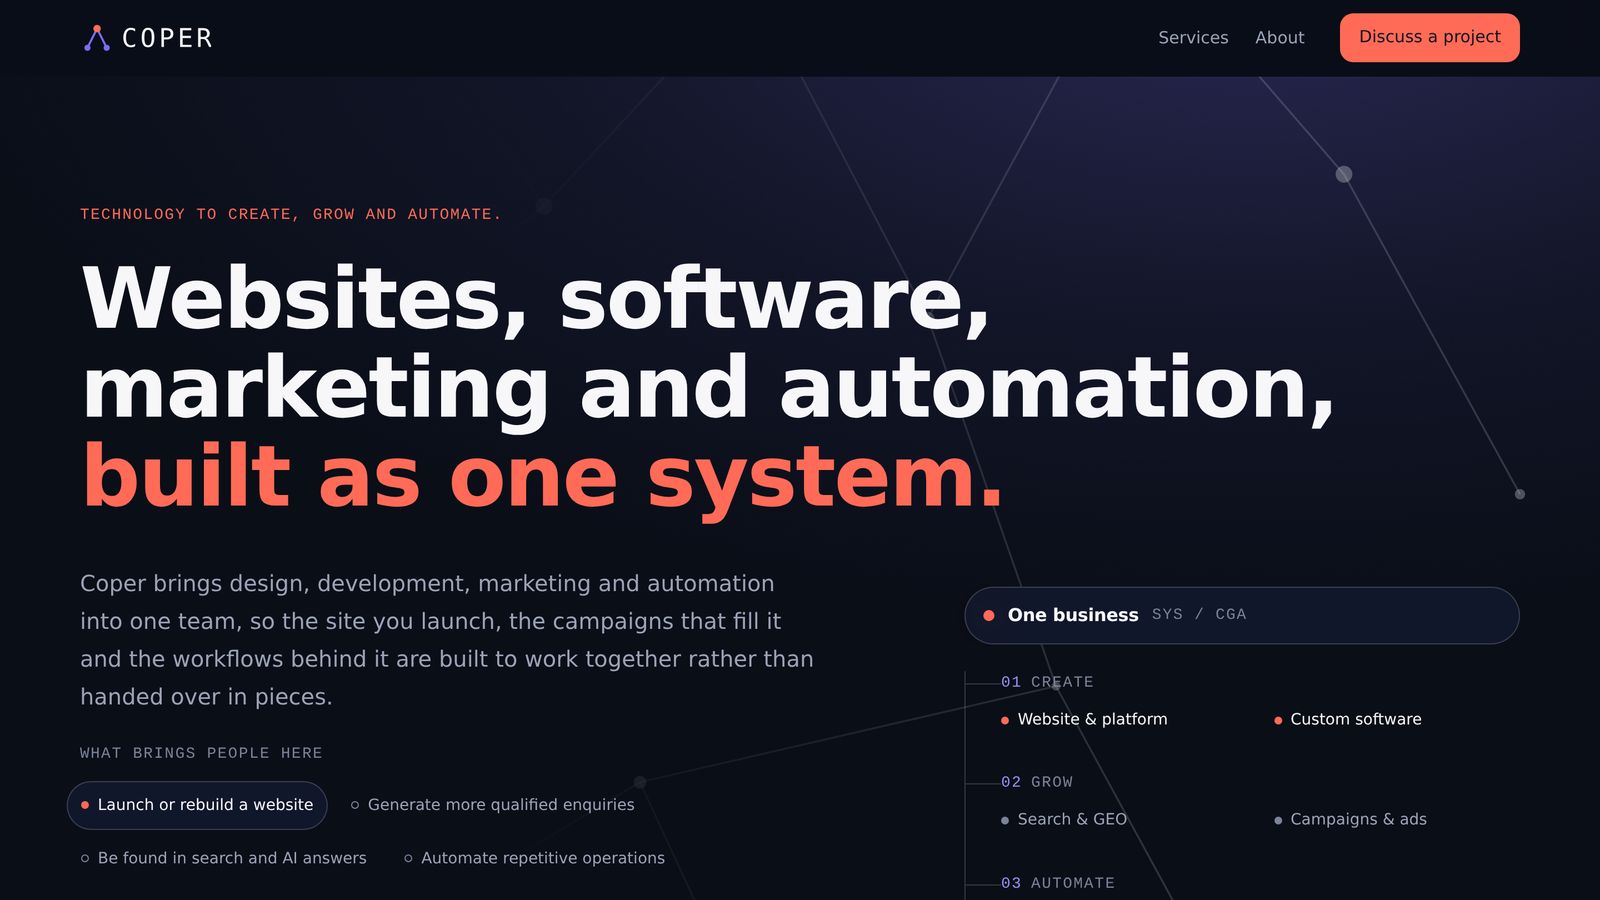
Before and after
The visual change is the easiest part to see. The bigger change sits underneath it.
Why now
Built for how businesses work now
Businesses increasingly run through connected flows — enquiries, quotes, reminders and follow-ups, many of which can be automated. We rebuilt Coper so the website becomes a foundation for that automation from day one.
Automation designed in, not bolted on
The enquiry flow is built as a system from the start, not added around a standalone form later.
Room for what comes next
You do not need to know every tool you'll use in three years. The foundation should make future integrations easier to add, not harder.
Create, Grow and Automate on one foundation
The website, search structure and enquiry flow are built to work together, giving future marketing and automation something structured to connect to.
A clearer Coper
The old site sold one thing. The new one sets out what Coper actually does, and how the parts connect.
- Create, Grow and Automate presented as one connected offer
- Websites, software, marketing and automation described together
- Every service page written to the same structure
Search built into the foundation
Search was designed into the structure of the site rather than added after launch.
- Every page has one subject it is meant to be found for
- The build refuses to publish two pages competing for the same subject
- Sitemap, indexing and canonical controls are generated from the site itself
- Case studies are written to strengthen service pages, not compete with them
- Search Console connected, so later decisions rest on real data
Pages built as a system
A new page inherits the foundations instead of rebuilding them by hand every time.
- Pages are built from shared, checked content records
- Structure, metadata and publication controls come with the page
- Adding a page does not mean redoing the technical work
Checks that run before anything publishes
Every change has to pass automated checks before it can reach the public site. They are a guard rail, not a guarantee.
- Search — indexing, metadata and which page owns which subject
- Content — claims, publishing readiness and how proof is classified
- Quality — accessibility, links, images and visual changes
- Release — the production candidate is checked before it goes live
In progress
A foundation that keeps earning
The rebuild left behind systems that keep earning after launch. None of these is finished, and each is worth more the longer it runs.
Search gets sharper with data
Search Console is connected and data is still accumulating. There is nothing meaningful to report from it yet; when there is, it shapes content and search priorities around what people actually search for.
Reusable foundations keep growing
The parts of this build that are not specific to Coper are being turned into a foundation other sites can start from. The audit is done and the boundaries are drawn; nothing has been reused on another site yet.
Automation takes over repeated work
A repeatable project setup — the control documents, checklists and working rules a new site starts from — exists and has been used here only. More repeated checks can move into it over time.
Capabilities
What this project covers
- CreateBuild what your business needs
- GrowGet found and win more customers
- AutomateSave time and run your business better
Evidence
What this shows
Directly observable
- The before and after are both directly observable: the previous site was rebuilt from its source and captured, and the current site is live
- The enquiry form works with JavaScript switched off
- The site sets no cookies and stores nothing in the browser
- Every page states plainly whether search engines may index it, and the sitemap contains exactly the pages that say yes
What we are measuring next
The system is live; the results are not in. We are not claiming ranking, traffic or enquiry improvements before the data supports them, and no performance comparison between the two sites has been measured.
Under the hoodThe full list of what was built, and what we are not claiming
Everything this included
- A site built and owned outright, rather than generated from a template
- Pages built from shared content records, so a new page inherits the same structure, metadata and publication controls instead of being rebuilt by hand
- Search built into the foundation: every page has one subject it is meant to be found for, and the site refuses to publish two pages competing for the same one
- Indexing, sitemap and canonical controls generated from the site itself, so what search engines are told always matches what was actually published
- Singapore language and location signals set once and applied consistently, rather than page by page
- Case studies written to strengthen the service pages they relate to, instead of competing with them for the same search terms
- Enquiries stored in a database, with the sender only told it worked once the record is safely saved
- A scheduled job that retries failed deliveries and deletes enquiries once they pass their retention period
- Automated checks before anything is published: accessibility, every internal link, page structure, images, wording rules, and exactly which pages search engines may see
- Wording rules that refuse to publish a statistic, a client name, an award or an outcome that is not backed by a record
- A release process that ties every published version to the exact source it was built from, and refuses to publish one it cannot account for
- A move to new hosting with the previous site kept live as a rollback
- Search Console connected and the sitemap submitted, so later decisions can be made on real data rather than assumptions
What is not claimed
- No speed, traffic, ranking, click-through or enquiry-volume comparison has been measured between the two sites, and none is claimed here
- The search work is a foundation, not a result. The site is built to be found and to be measured; it has not been running long enough to say what that has earned
- The screenshots show a change in design and positioning. They are not evidence that one site performs better than the other
- The reusable foundation has not been used to build another site. What exists is the audit, the boundaries and the project setup — not a finished product
- Enquiry notifications are not automated yet — submissions are stored reliably and checked by a person on a fixed daily routine
- The automated checks cover the mistakes we could describe in advance. They are a guard rail against the ordinary accidental error, not a guarantee that everything published is correct
Related
The services behind this work
If you are working out whether something along these lines is worth building, we are happy to talk it through — including the parts that would not be worth doing.
Discuss a project